The race video commentary is my own voice, cloned zero-shot in Chatterbox by ResembleAI from three reference recordings at three energy levels. Claude writes each line from race facts that Python works out first.
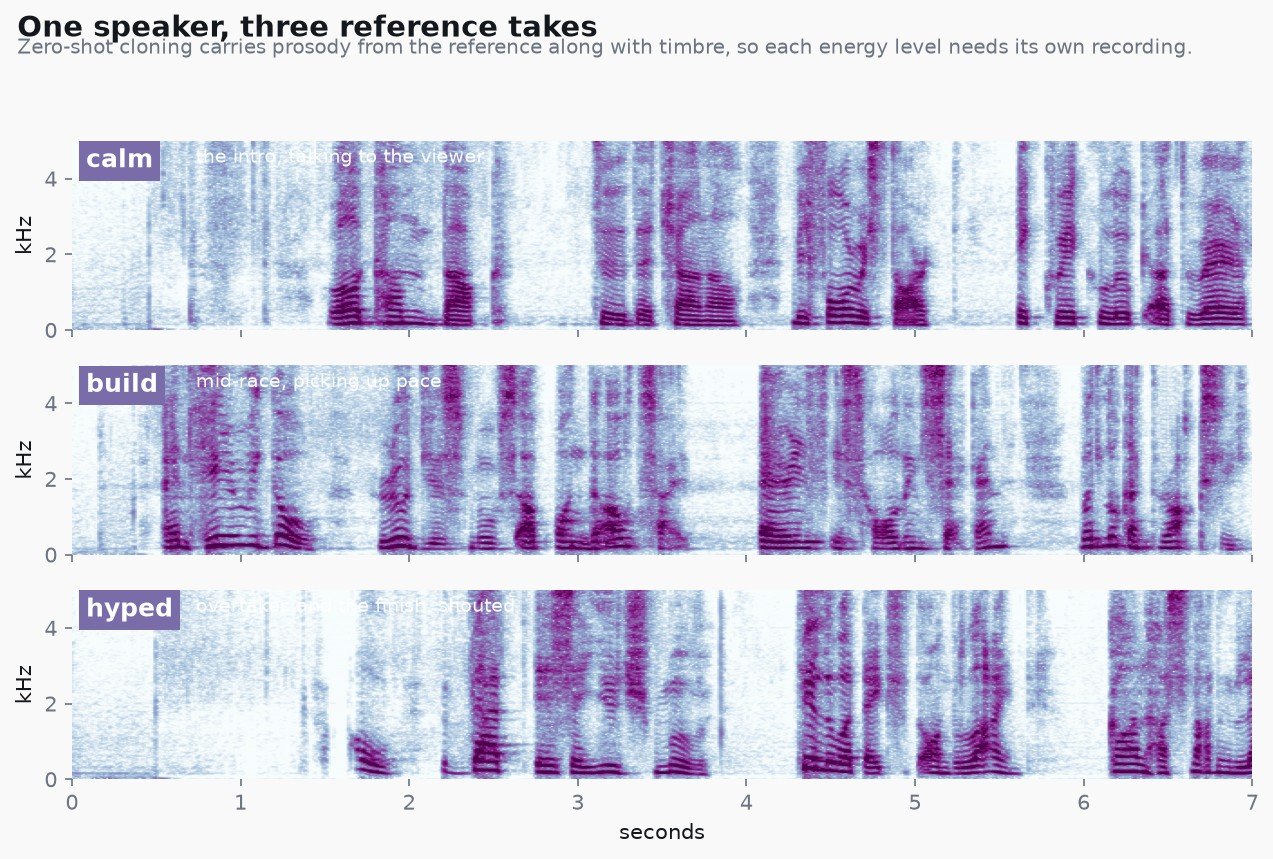
A flat sample gives a flat clone at every setting
Zero-shot cloning copies prosody along with timbre, so exaggeration cannot add energy the reference recording does not contain.
- The first setup used one recording plus
exaggeration, a parameter that raises delivery energy. - Now there are three recordings, same person, same microphone:
calmfor the intro,buildmid-race,hypedfor overtakes and the finish. - Every script line is tagged with one, so the energy shifts the way a real broadcast does.
- The settings still apply on top of each recording:
| style | exaggeration | cfg_weight |
|---|---|---|
| calm | 0.50 | 0.50 |
| build | 0.90 | 0.40 |
| hyped | 1.10 | 0.35 |
Python works out what happened, Claude only writes it down
If something is not in the fact list Python computes, it cannot end up in the commentary.
- Reading a race is math: who led at nine seconds, who climbed the most, how big the final gap was.
- Given raw numbers, a language model writes an excited call about an overtake that never happened.
- Claude turns the fact list into eight short lines that sound natural said aloud.
- The model never writes the first and last lines, "Did the chat pick your favorite?" and "Did yours win?". Those belong to the channel.
Each line is capped at 9 words and 48 letters
Letters predict speaking time better than words, so the letter limit does most of the work.
- Lines sit at eleven fixed times, about three seconds apart.
- The first rule was a 10-word limit. The Tokyo Revengers script stayed under it and still ran eight seconds long.
- A line like "Ken Ryuuguji closing in on Manjirou Sano" fits the word limit and is still a mouthful.
- A cloned voice takes 40 to 65 percent longer to say the same words.
Every line is recorded before it is scheduled
The schedule is built from real clip lengths, and a line that runs into the next one pushes it later.
- Chatterbox pads a random amount of silence onto each clip.
- It sometimes makes a bad take: the same six-word line once came out at 0.39 seconds.
- Each line is generated several times and picked by length.
- Under the same limits, lines running long range from 0 of 11 to 6 of 11.
One narrator for every series
My voice is the narrator on every series.
- The built-in Chatterbox voice reads the same numbers well.
- That consistency is the part of the race videos I am most pleased with.
- Nothing waits on Chatterbox here. Where a person waited, it lost to Kyutai's engine by eight seconds per turn.
- The music underneath is made locally too.